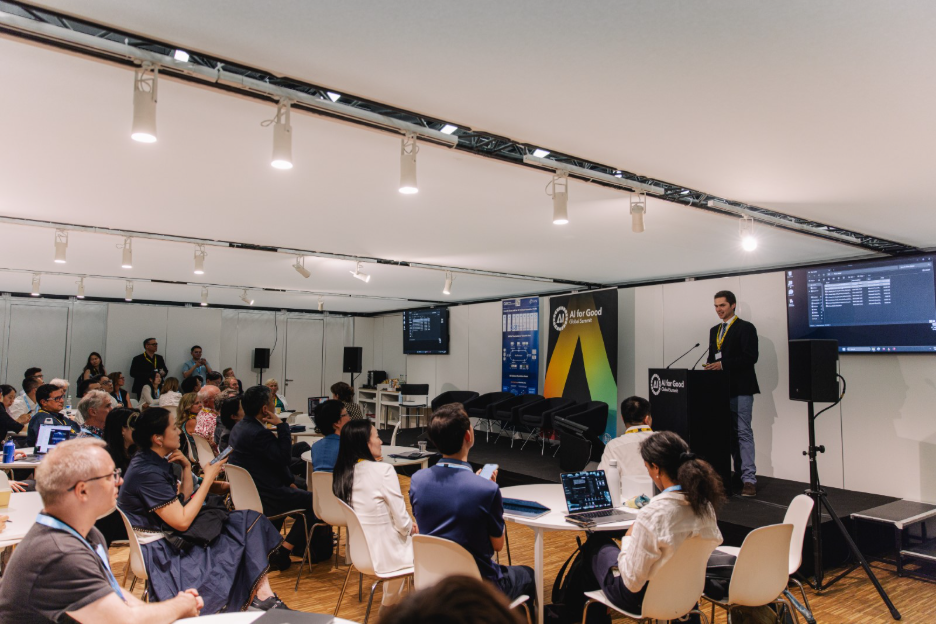
Different sciences record their observations in different forms. Chemistry uses molecular formulas; genomics uses sequences; astronomy uses images and spectra; geosciences use maps. Models trained on one of these forms rarely transfer to another. The workshop “021 Scientific Foundation Model: Empowering the transformation of scientific research paradigms,” organised in partnership with Zhejiang Lab during the AI for Good Global Summit 2026, explored whether these scientific “languages” could be brought into a shared AI framework.
Moderated Anna Stepashkina, Research Expert at Zhejiang Lab, the workshop presented the 021 Scientific Foundation Model and applications spanning chemistry, life sciences, astronomy, mathematics, and materials science. Across the different fields, the central question remained the same: could a shared model help scientists connect information that has traditionally been analyzed in isolation?
In opening remarks, Ms. Tong Weiling, Director General of the Zhejiang Provincial Department of Science and Technology, described Zhejiang Lab’s Model Scope community as the largest open-source model community in China and the second largest in the world. She proposed four areas for international cooperation: joint research on shared scientific questions, cross-border data sharing and joint labelling, exchange of researchers and students, and shared governance of open-source science foundation models.
A unified representation for scientific data
Guirong Xue, Chief Engineer for Science Models at Zhejiang Lab, presented the 021 Scientific Foundation Model as an attempt to bring text, code, mathematics, physical formulas, chemistry, astronomy, geoscience, life science and materials science into a single shared representation. Scientific research rarely relies on one form of data alone. A biological question, for example, may require genomic sequences, protein structures, scientific papers, experimental records, and knowledge from several disciplines.
Xue described two design choices as central: a unified tokeniser that converts each data type into a common representation before training, and a mixture-of-experts architecture in which specific experts are activated for specific tasks while allowing knowledge to be shared across domains. The team released base models with 32 billion and 236 billion parameters. On a genomics benchmark, Xue reported that the unified model outperformed both specialised genomic models and larger general-purpose language models.
Narrowing large search spaces
Several presentations showed how scientific foundation models could help researchers explore possibilities too numerous to examine manually.
Sebastian Viktor Pios Senior Research Fellow at Zhejiang Lab presented a chemistry model built on the same foundation. Chemistry involves many ways of representing molecules, a rapidly expanding research literature, and an immense number of possible molecular structures. According to Pios, the model performed comparably to two leading commercial systems on molecular understanding and outperformed both on property prediction despite its smaller size. He described a collaboration with a Chinese chemical company that used the model to screen candidate refrigerants down to a shortlist of 60 for further computational and experimental work.
Shiping Liu, Chief Scientist at BGI Research, described GenesLM, a human-genome foundation model trained on more than 60 complete human genomes, and TransGene, a joint text-and-sequence model developed with the Zhejiang Lab team. He described the platform’s application to a tumour patient in which 1.5 terabytes of multi-omics data yielded 34 high-confidence therapeutic targets, one of which is being taken forward by a Chinese group toward messenger-RNA and dendritic-cell-based therapies.
In both cases, the models were presented as tools for narrowing the number of possibilities requiring further computational, laboratory, or clinical investigation.
Combining complementary data
Astronomy offered another example of the value of shared representations.
Emma Tolley, Assistant Professor at EPFL, presented the One Astronomy foundation model, which combines image and spectral data to search for gravitational lenses. On a curated evaluation set, Tolley reported that combining the two modalities gave a precision of 83%, compared with about 32% for image data alone, 43% for spectra alone, and 2% to 5% for the standard convolutional-network baseline. The result reflected one of the workshop’s central arguments: scientific data types that provide incomplete answers separately may become more informative when interpreted together.
Jifeng Liu of the National Astronomical Observatories of the Chinese Academy of Sciences presented the One Universe, an initiative combining astronomical data, models, facilities, and agent-based tools in a platform intended to widen access to research. He described the case of a dentist who examined public astronomical data in his spare time and contributed to the discovery of what the team described as the early stages of an Earth-Moon-type system forming around a distant young star. The example showed how platforms bringing together data, models, and scientific knowledge could allow people outside traditional research pathways to contribute to discovery.
From generated answers to verified results
The workshop also examined how AI-generated scientific outputs can be tested.
Lei Zhang, Associate Professor of Mathematics at the National University of Singapore, presented work on formal mathematical reasoning built on the 021 base model. According to Zhang, a multi-agent proof system produced a derivation of a formula that had previously taken a doctoral student approximately one year to establish; the system produced an equivalent result in a day.
Anna Stepashkina presented One Porous, an agent for designing porous materials. The system generated a structure that was subsequently produced through 3D printing and tested experimentally. Stepashkina reported that the structure was used in the design of a satellite component, reducing its mass by approximately 10 percent and shortening the production cycle from three months to two weeks..
Building an open scientific ecosystem
The session then turned data access through a roundtable discussion moderated by Richard Chuchla, Co-chair of the GeoGPT Governance Committee. Ms. Susanne Pedersen, Director of the Centre for Science and Knowledge at the International Union for Conservation of Nature (IUCN), said the IUCN holds 76 years of biodiversity records and is working to make its data sets AI-ready.Tomasz Kacprzak, professor for High-Performance Computing at the University of Applied Sciences and Arts Northwestern Switzerland, said AI applied to the same cosmological data has extracted approximately twice as much information as previous methods. Amal Kasry, CHIEF of Section for Basic Science, Research, Innovation and Engineering, raised concerns about the concentration of AI training data and infrastructure in a limited number of countries and companies. She described UNESCO initiatives providing researchers in the Global South with remote access to research facilities and high-performance computing.
The discussion also addressed standards, open access, reproducibility, intellectual property, and the need for scientists with domain expertise to work closely with AI developers.
Across the workshop, the 021 Scientific Foundation Model was presented not simply as one model for many tasks, but as shared infrastructure through which scientific data, knowledge, and methods could be connected. Its applications illustrated different parts of that proposition: narrowing large search spaces, combining complementary data, widening access to research tools, and accelerating work that can then be verified through formal, computational, or experimental methods.
For this approach to develop across scientific fields, models alone will not be enough. Progress will also depend on reliable data, access to computing resources, common standards, international cooperation, and the judgment of scientists who understand the questions being asked.